
 back to blog
Unleashing transformers: parallel token prediction with discrete absorbing diffusion for fast high-resolution image generation from vector-quantized codes
Summary
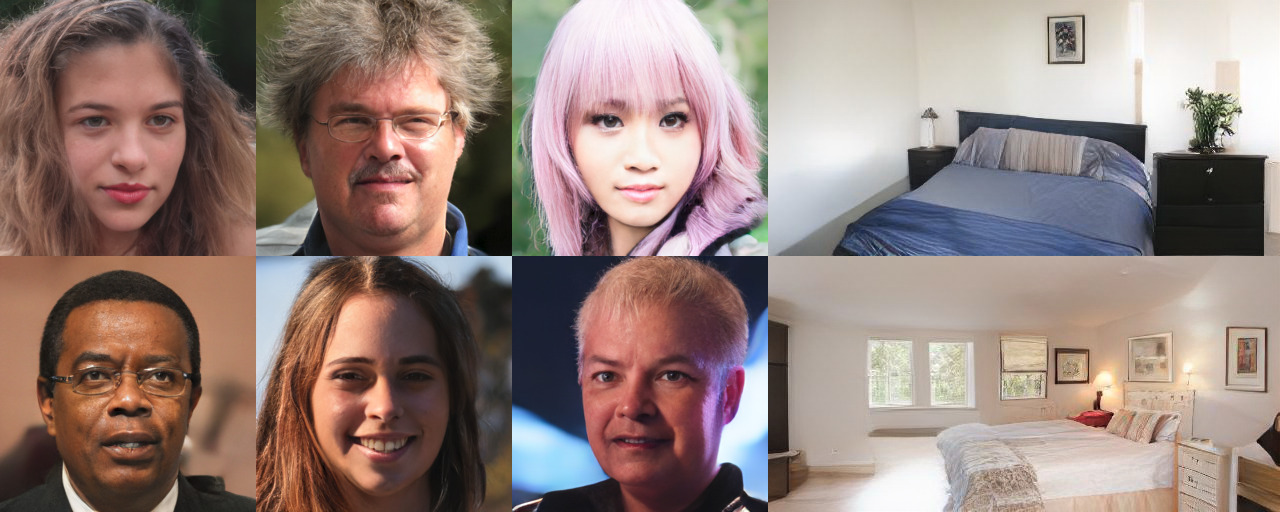
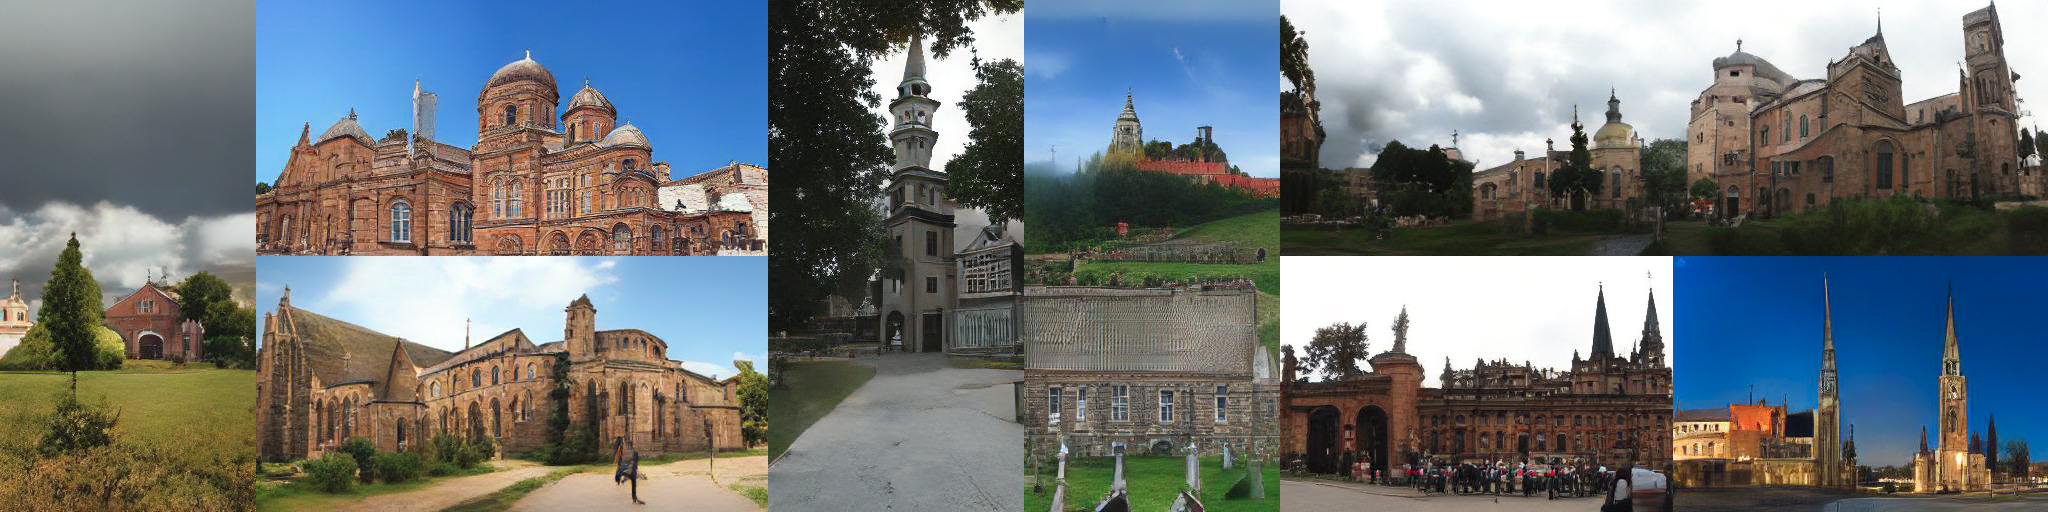
Accepted at ECCV. We propose a novel parallel token prediction approach for generating VQ image representations that allows for significantly faster sampling than autoregressive approaches. Our approach achieves state-of-the-art results and can generate high-resolution images surpassing the original training data's resolution.
Approach
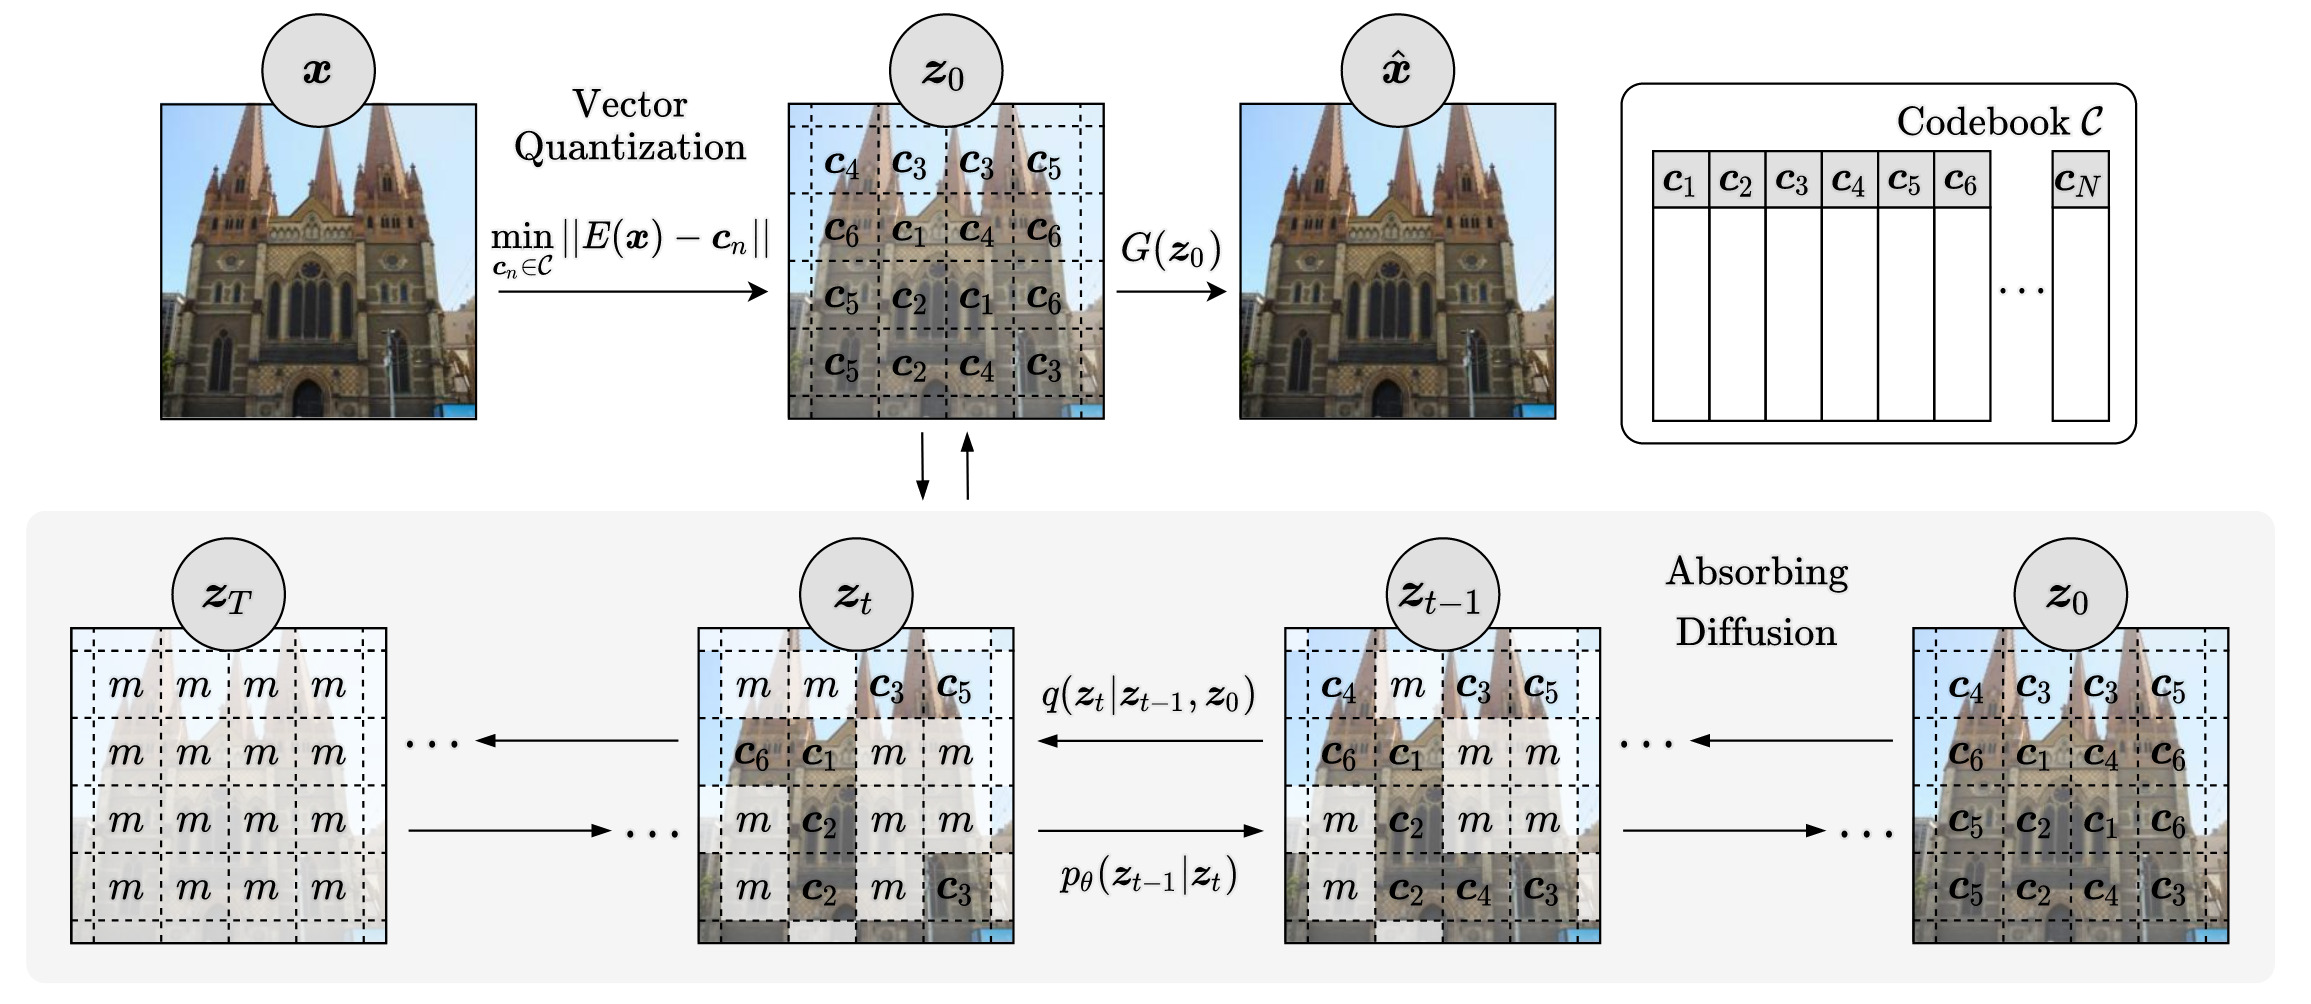
We utilize a Vector-Quantized (VQ) image model to compress images into a discrete latent space. An absorbing diffusion model then learns the latent distribution, allowing us to generate high-resolution images rapidly, without the need for time-consuming autoregressive methods.
Evaluation
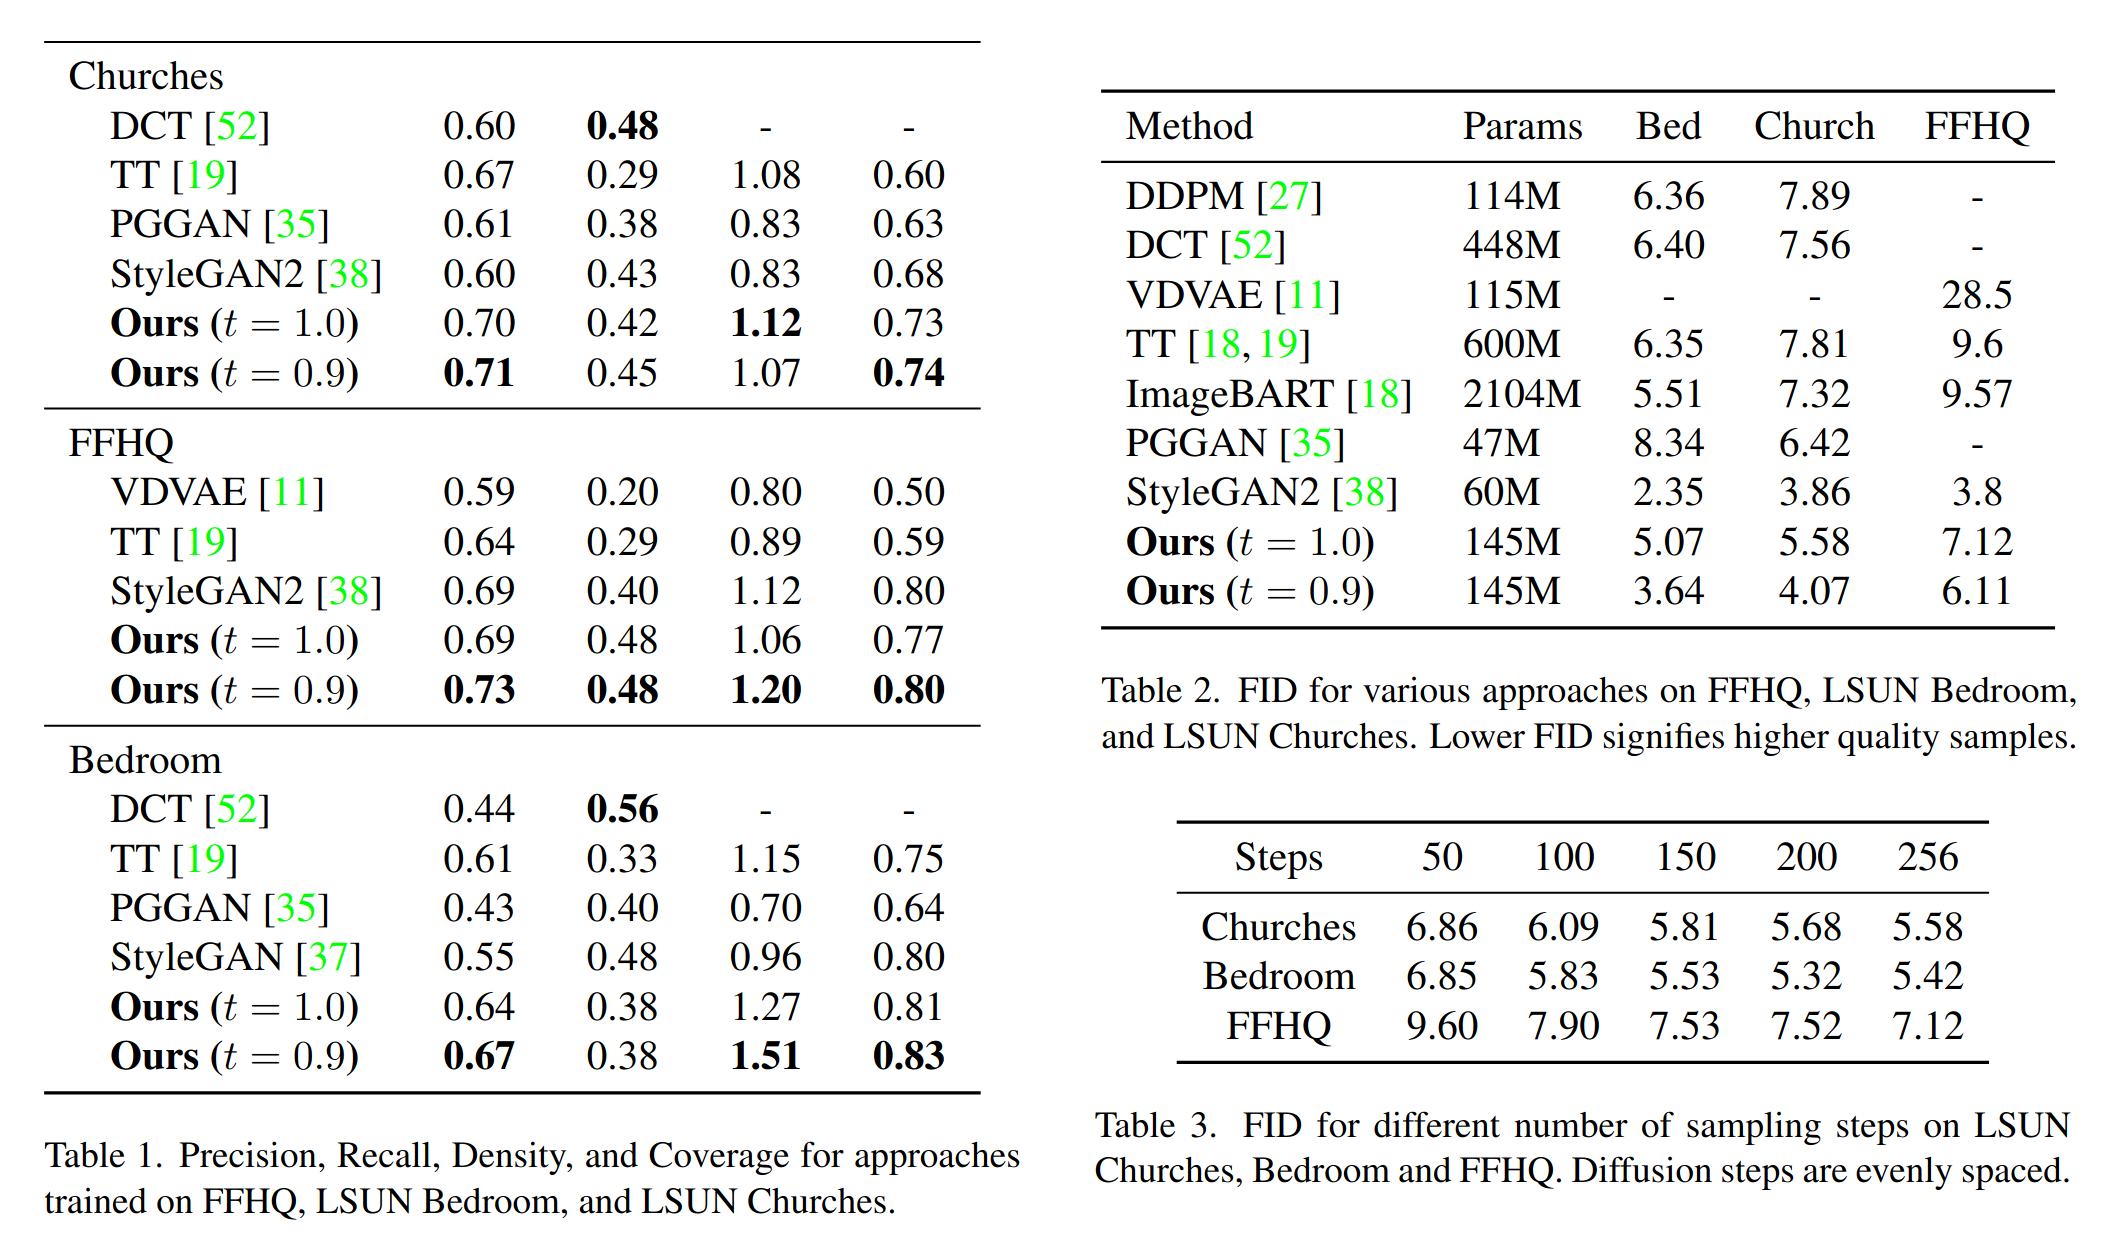
Our method has been rigorously evaluated on multiple high-resolution datasets, including LSUN Churches, LSUN Bedroom, and FFHQ. Despite its efficiency and reduced parameter count, our approach achieves comparable or better results against other VQ image models.
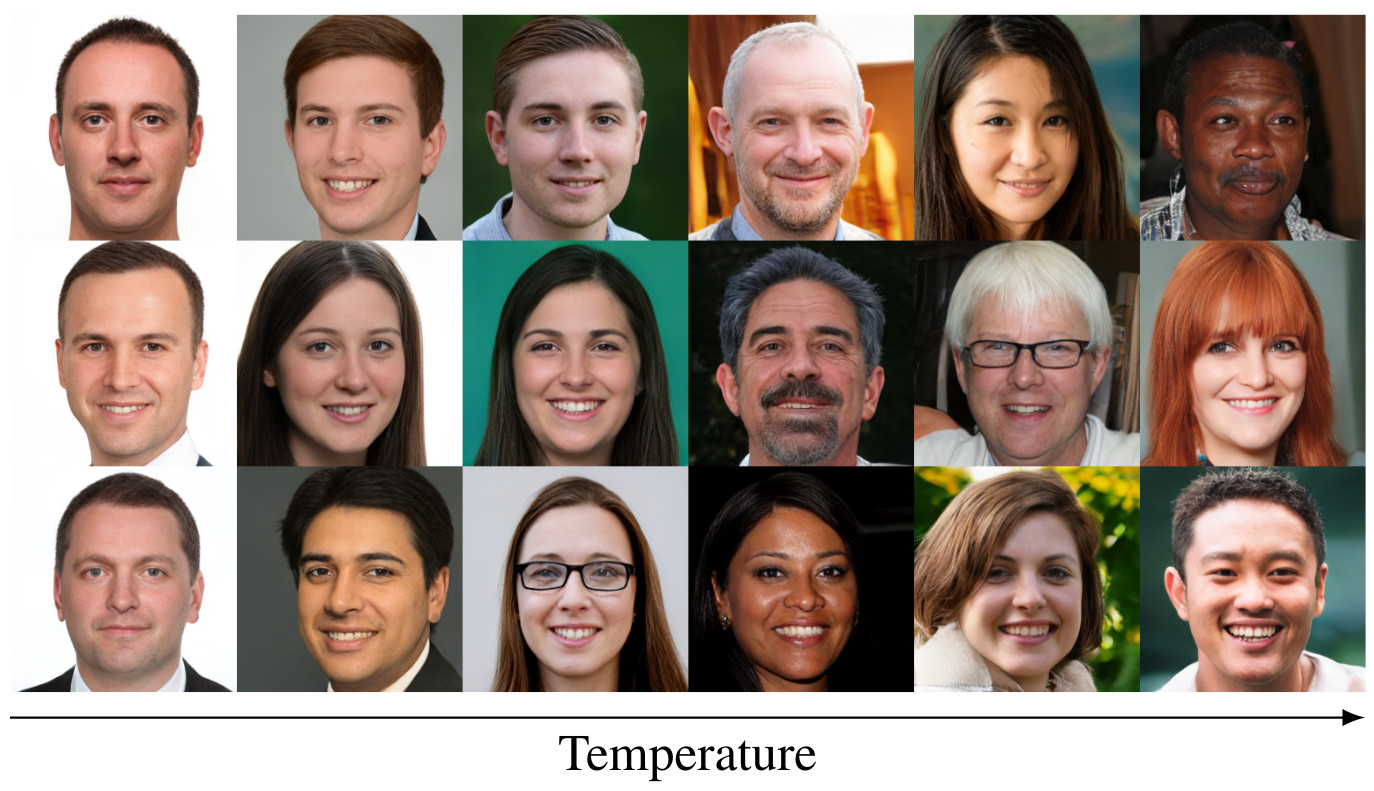
We also support outpainting (synthesise image regions outside the training data), inpainting, and control over the sample diversity.
Citation
Please cite the article with:
@inproceedings{bond2022unleashing,
  title={Unleashing Transformers: Parallel token prediction with discrete absorbing diffusion for fast high-resolution image generation from vector-quantized codes},
  author={Bond-Taylor, Sam and Hessey, Peter and Sasaki, Hiroshi and Breckon, Toby P and Willcocks, Chris G},
  booktitle={European Conference on Computer Vision},
  pages={170--188},
  year={2022},
  organization={Springer}
}